
Selected Publications
Google Scholar snapshot on 2026-06-06: 17 publications, 562 citations, h-index 9.
SelfLift: Accelerating Few-Step Diffusion via Self-Recovering Resolution Transition
Status: arXiv 2026 · Topic: few-step diffusion acceleration
Introduces self-recovering progressive-resolution transitions for few-step diffusion, enabling late low-to-high-resolution lifting while preserving generation quality.
ReTrace: Rejected-Trajectory Conditioning for Speculative Decoding
Status: arXiv 2026 · Topic: speculative decoding
Reuses rejected draft trajectories as cross-round conditioning, improving acceptance length and decoding speed without changing lossless target-side verification.
Accelerating Unified Multimodal Models with Core-Expansion Routing and Unified Computation Scheduling
Status: arXiv 2026 · Topic: unified multimodal model acceleration
Combines task-shared core routing with progress-conditioned expansion and unified scheduling across tokens, layers, FFNs, caches, and denoising steps.
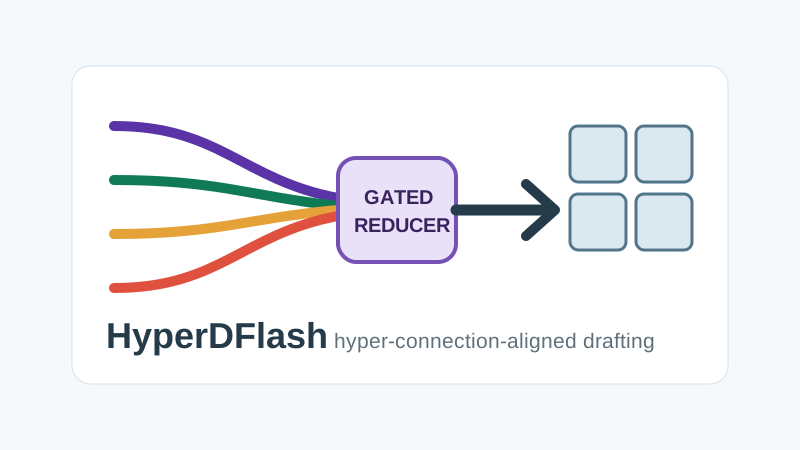
HyperDFlash: Hyper-Connection-Aligned Block Speculative Decoding with Gated Residual Reduction
Status: arXiv 2026 · Topic: architecture-aligned speculative decoding
Aligns block-parallel drafting with multi-hyper-connection residual streams through pre-collapse conditioning, lightweight gated reduction, and targeted distillation.

DreamLite: A Lightweight On-Device Unified Model for Image Generation and Editing
Status: ECCV 2026 · Topic: on-device image generation and editing
Presents a SOTA on-device unified model for image generation and editing, targeting practical mobile deployment with strong quality-efficiency trade-offs.

TCEC: Error Propagation Mechanisms and Compensation Strategies for Quantized Diffusion
Status: ICML 2026 Spotlight + Oral, Top 0.7% · Topic: diffusion quantization
Studies how quantization errors propagate across diffusion timesteps and proposes timestep-aware compensation strategies for efficient low-bit generation.

Motion-Aware Caching for Efficient Autoregressive Video Generation
Status: ICML 2026 · Topic: video generation cache reuse
Uses motion-aware token update scheduling to reduce redundant computation in autoregressive video generation while preserving temporal quality.

S2O: Early Stopping for Sparse Attention via Online Permutation
Status: ACL 2026 Oral · Role: co-first author; Project Lead (LD) · * equal contribution
Introduces online permutation and early-stopping mechanisms for sparse attention, reducing attention computation while keeping model quality stable.

ERTACache: Error Rectification and Timesteps Adjustment for Efficient Diffusion
Status: ICLR 2026 · Role: co-corresponding author · † co-corresponding author
Combines timestep adjustment with online error rectification to make diffusion cache reuse more robust under aggressive acceleration settings.

Seedance 1.5 Pro: A Native Audio-Visual Joint Generation Foundation Model
Status: arXiv 2025 · Topic: audio-visual generation foundation model
Reports a native audio-visual joint generation foundation model and the production-oriented optimization stack behind efficient deployment.
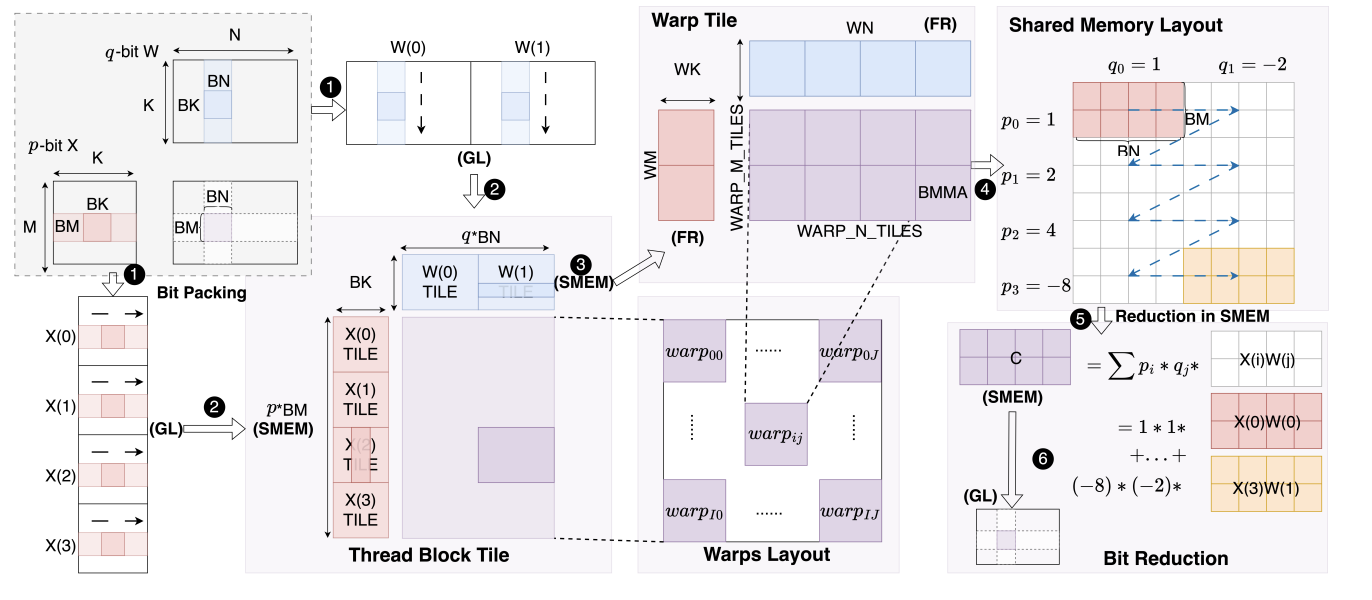
ABQ-LLM: Arbitrary-Bit Quantized Inference Acceleration for Large Language Models
Status: AAAI 2025 · Role: co-first author · * equal contribution
Enables arbitrary-bit LLM inference acceleration through hardware-aware dynamic quantization and latency-optimal bit allocation.
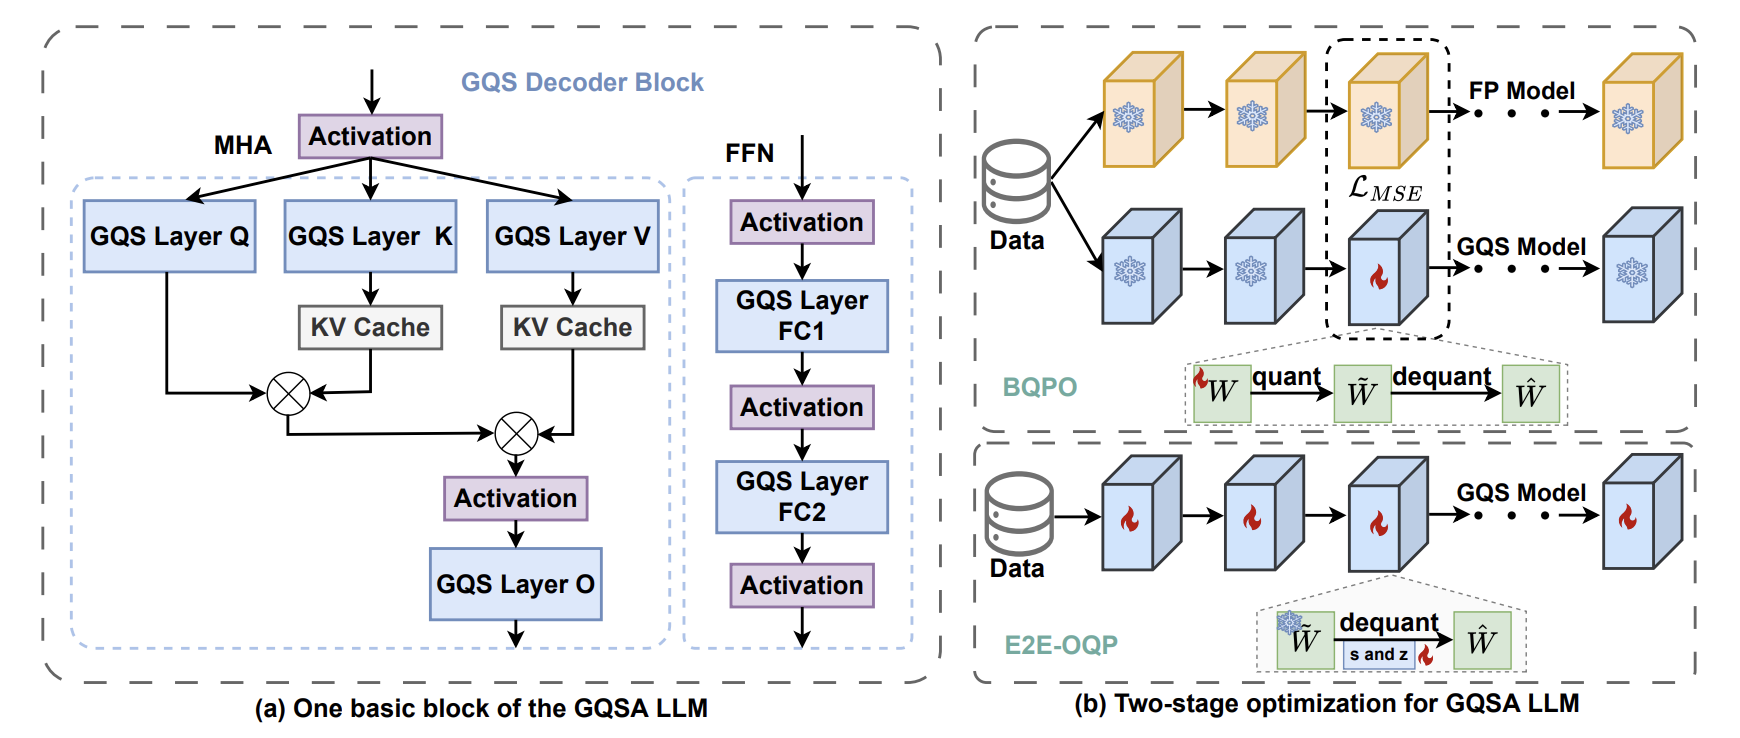
GQSA: Group Quantization and Sparsity for Accelerating Large Language Model Inference
Status: IJCNLP-AACL 2025 · Award: Best Paper Honorable Mention · * equal contribution
Explores group sparsity beyond conventional 2:4 sparsity, combining algorithm-level sparsification with customized inference kernels.

Lightweight Error-Tolerant Edge Detection Using Memristor-Enabled Stochastic Computing
Status: Nature Communications 2025 · Topic: efficient vision computing
Demonstrates lightweight, error-tolerant edge detection by combining stochastic computing with memristor-enabled hardware characteristics.
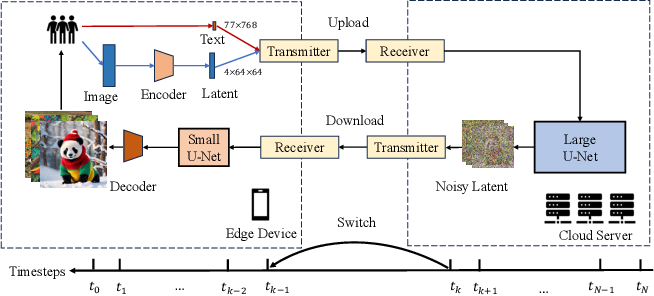
Hybrid SD: Edge-Cloud Collaborative Inference for Stable Diffusion Models
Status: arXiv 2024 · Role: co-first author · * equal contribution
Builds an edge-cloud collaborative inference framework for Stable Diffusion, balancing mobile latency, cloud quality, and deployment cost.
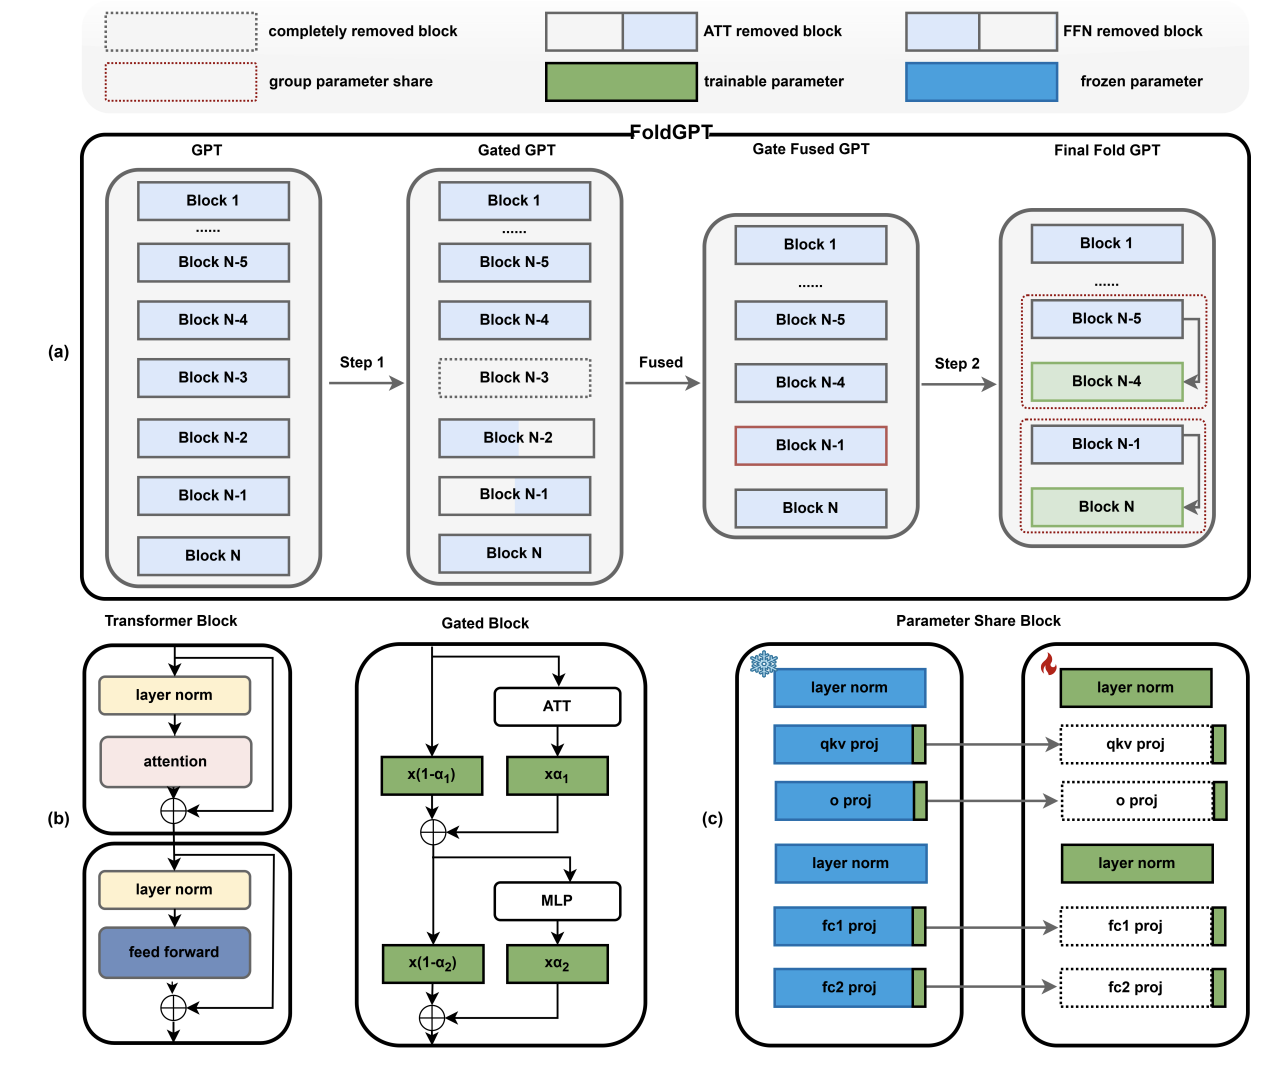
FoldGPT: Simple and Effective Large Language Model Compression Scheme
Status: arXiv 2024 · Role: co-first author · * equal contribution
Provides a simple LLM compression scheme that folds model structure and parameters for efficient inference-oriented deployment.
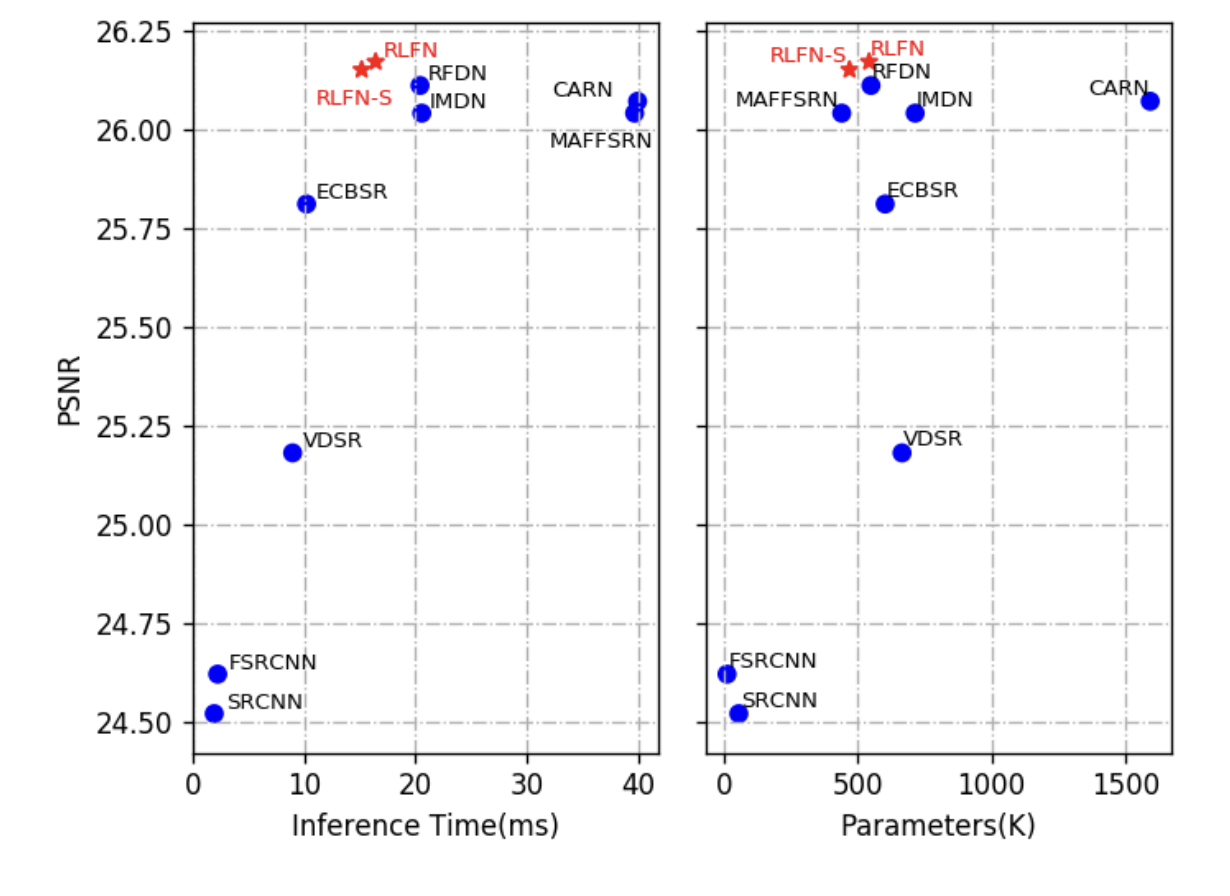
Unfolding Once is Enough: A Deployment-Friendly Transformer Unit for Super-Resolution
Status: ACM-MM 2023 · Topic: deployment-friendly super-resolution
Designs a practical transformer unit for super-resolution that improves deployment efficiency while retaining reconstruction quality.

SparseByteNN: A Novel Mobile Inference Acceleration Framework Based on Fine-Grained Group Sparsity
Status: arXiv 2023 · Role: co-first author · * equal contribution
Introduces fine-grained group sparsity and a mobile inference acceleration framework for efficient on-device neural network deployment.
Residual Local Feature Network for Efficient Super-Resolution
Status: CVPRW 2022 · Role: co-first author · * equal contribution
Establishes a lightweight super-resolution baseline with strong quality-efficiency trade-offs and practical production deployment value.

NTIRE 2022 Challenge on Efficient Super-Resolution: Methods and Results
Status: CVPRW 2022 · Topic: efficient super-resolution challenge
Summarizes NTIRE 2022 efficient super-resolution methods and results, including the champion solution adopted as a practical ESR baseline.

MixSearch: Searching for Domain Generalized Medical Image Segmentation Architectures
Status: arXiv 2021 · Topic: medical image segmentation NAS
Searches architectures for domain-generalized medical image segmentation, improving robustness across dataset and domain shifts.

Binary Convolutional Neural Network with High Accuracy and Compression Rate
Status: ICCA 2019 · Topic: binary neural network compression
Studies high-compression binary convolutional networks and accuracy-preserving model compression for efficient inference.